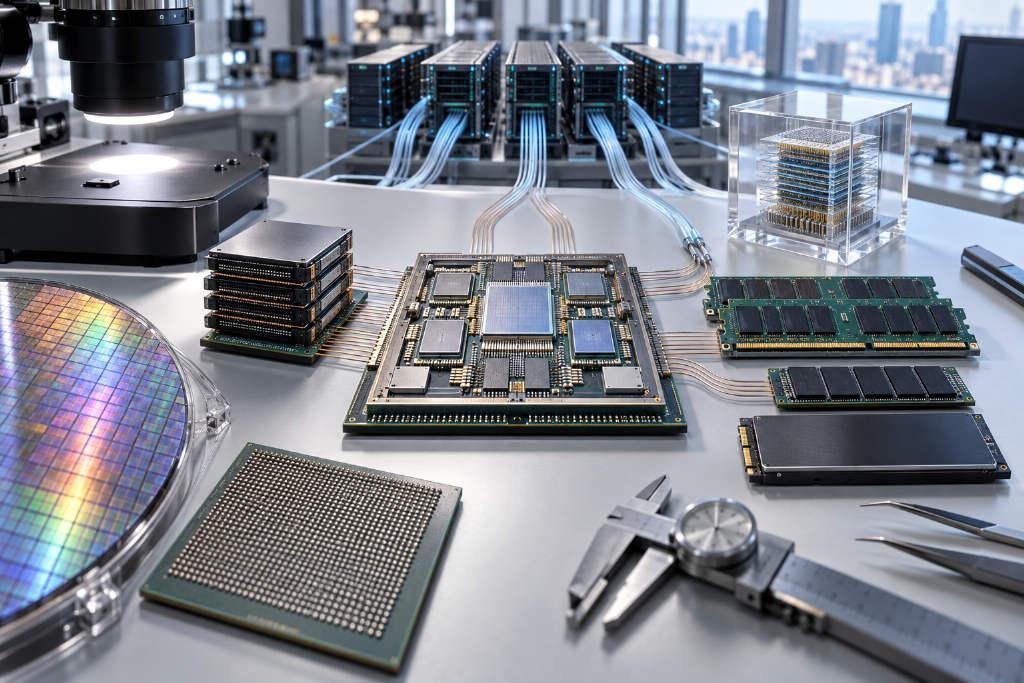
Chip expert says AI compute bottlenecks are shifting to packaging, interconnects and memory

Chip expert says AI compute bottlenecks are shifting to packaging, interconnects and memory

N
News Editor
2026-09-22 04:52:52
Veteran chip designer and hardware analyst Mr. Bubble said in an interview on the Frictionless Podcast that the main constraint in AI compute infrastructure is no longer just raw chip performance. In his view, the pressure point is moving toward advanced packaging, system-level interconnect latency and memory hierarchy management. He said rising costs at advanced process nodes and limited gains in transistor density are creating an economic challenge for the traditional Moore’s Law path, pushing the industry to connect multiple chips into a larger computing system through advanced packaging instead of relying only on smaller process nodes. Mr. Bubble also argued that the basic unit of AI compute may shift from a single chip or server to a full rack, or even multiple racks, making PCB design, packaging and interconnect capability more important. On memory, he said expanding inference context windows mean large amounts of historical context should not all sit in expensive high-bandwidth memory, or HBM. He expects the industry to use flash offloading more often, keeping frequently accessed data in HBM while moving lower-frequency context to larger, cheaper storage tiers. He added that 3D DRAM could become an important direction for next-generation memory technology.

Veteran chip designer and hardware analyst Mr. Bubble said in an interview on the Frictionless Podcast that the core bottleneck in AI compute infrastructure is shifting away from simply increasing chip performance and toward advanced packaging, system interconnect latency and memory hierarchy management.

Mr. Bubble said the cost of advanced process nodes is rising quickly, while gains in transistor density are limited. That, he said, is creating an economic challenge for the traditional Moore’s Law model. Instead of relying only on smaller process nodes, the industry is increasingly using advanced packaging to link multiple chips into a single computing system.

The basic unit of AI compute may move to the rack level

He said the basic unit of AI compute in the future may no longer be a single chip or a single server, but a full rack or even multiple racks. In that setup, PCB design, packaging and interconnect capability would become key limiting factors.

Memory hierarchy is becoming a bigger issue

On memory, Mr. Bubble said that as inference context windows expand, large volumes of historical context should not all occupy expensive high-bandwidth memory, or HBM. He said the industry may increasingly adopt flash offloading, keeping high-frequency data in HBM while moving lower-frequency context to storage tiers with larger capacity and lower cost.

He also said 3D DRAM could become an important direction for next-generation memory technology.

System-level hardware design may gain weight in AI infrastructure

On AI infrastructure investment, Mr. Bubble said system-level hardware design will become more important as prefilling and decoding gradually move toward disaggregated architectures.

He added that compared with directly betting on large model companies, businesses with capabilities in hardware, packaging, memory and other critical infrastructure may play a longer-term role in the AI industry chain.

This article was originally published by Bit.Fan. For more cryptocurrency news and market insights, visit www.bit.fan.
200

Disclaimer:

The market information, project data, and third-party content displayed on this platform are for industry information sharing only and do not constitute any form of investment advice or return commitment.

Cryptocurrency trading carries high risks. Users should fully assess their risk tolerance and make independent decisions. All profits, losses, and legal responsibilities are borne by the users themselves.