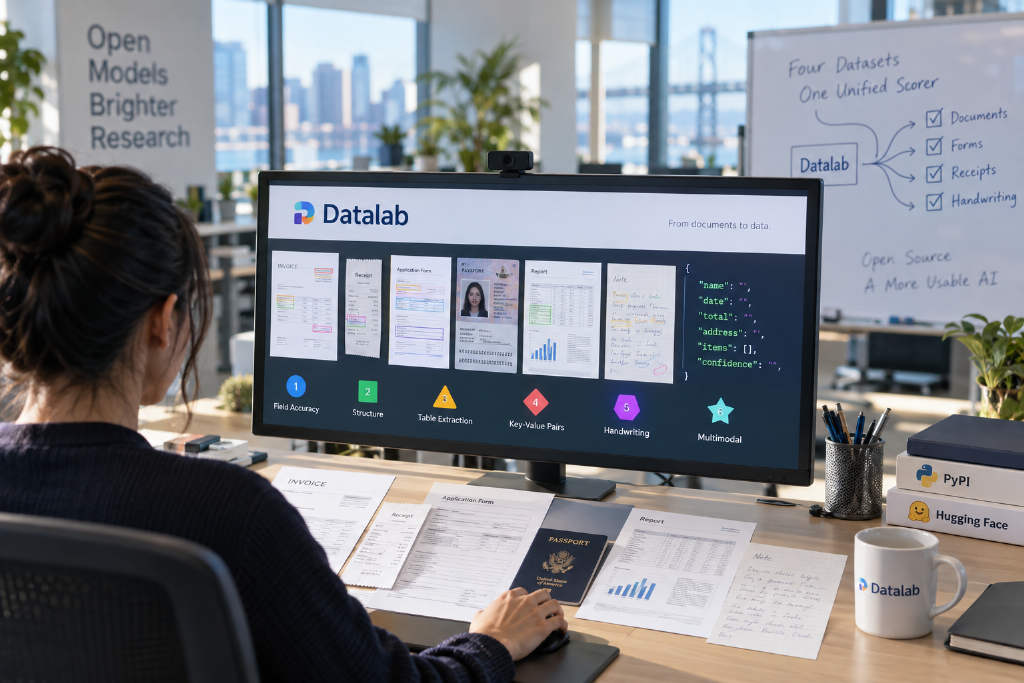
Datalab2026-10-02 15:29:17Datalab releases open-source OmniExtractBench for document extraction evaluationAI startup Datalab has introduced OmniExtractBench, an open-source benchmark suite designed to evaluate structured document extraction systems. The benchmark brings together 620 documents drawn from four existing benchmarks and uses a unified scorer to measure how accurately models fill a JSON schema. Datalab said the evaluation framework relies on six interpretable judgment types, aiming to make scoring easier to inspect and compare across systems. The company also argued that existing extraction benchmarks suffer from bias, opaque scoring methods, and limited document diversity. To address part of that workflow, OmniExtractBench uses the Hungarian algorithm for content-based row alignment. Datalab said the scorer is available through PyPI, while the dataset is hosted on Hugging Face under a CC BY 4.0 license. The development was cited by MarkTechPost.20