
Anthropic has reportedly started gray-testing Fable 5.2 across Claude Code, Claude Chat, and Claude Cowork, according to a MarsBit report that cited material from the WeChat account Xinzhiyuan. The piece said some requests that used to call Fable 5.1 are now being routed behind the scenes to Fable 5.2.
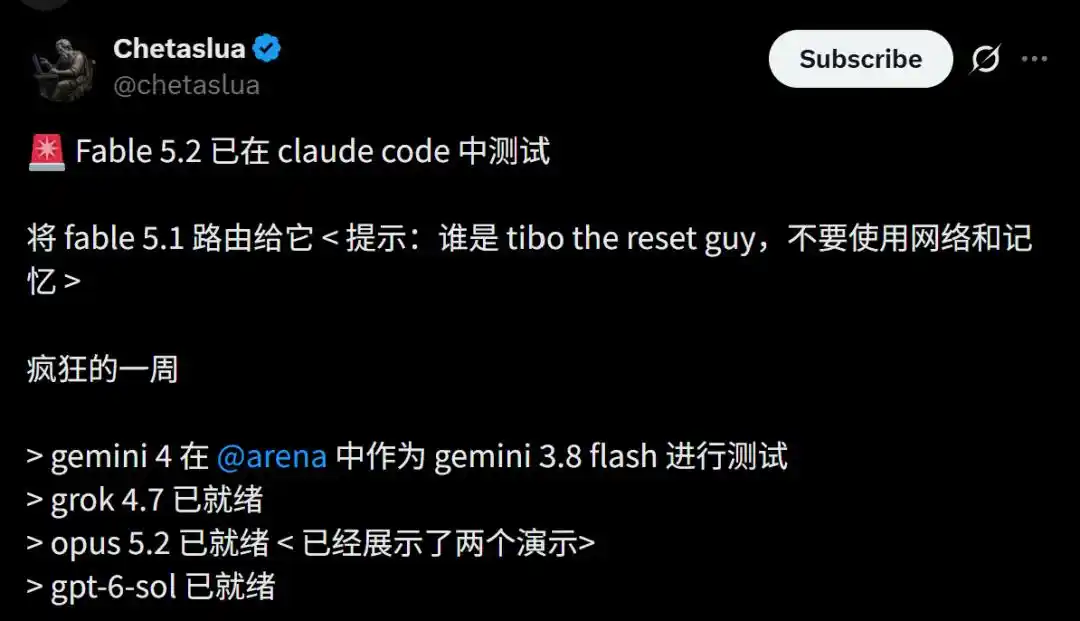
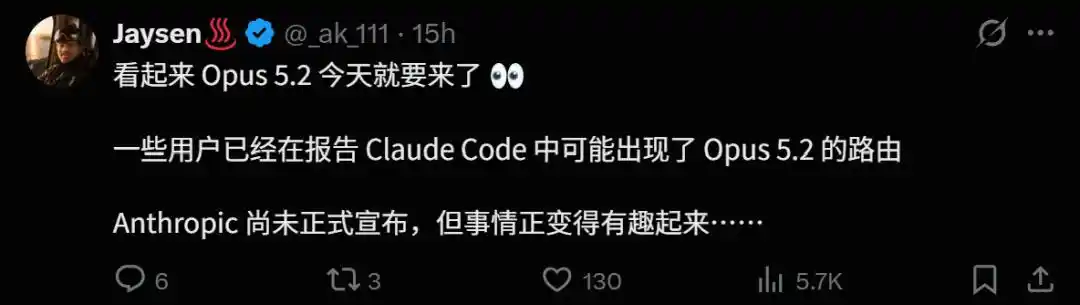
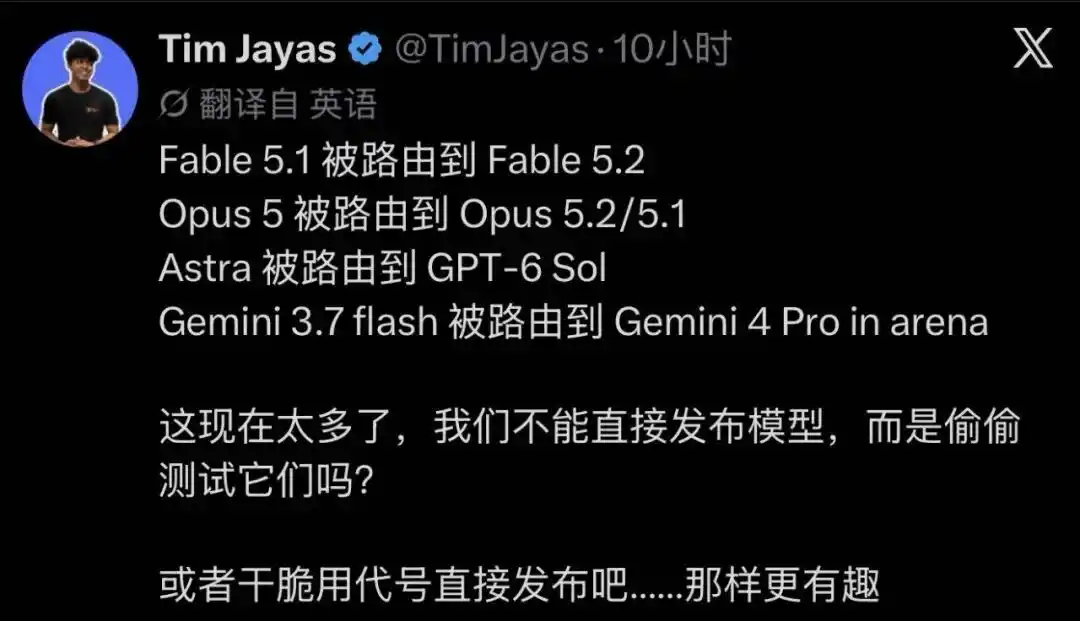
As more test cases popped up online, the article painted the change as a big leap, not some tiny point release. And it said Opus 5.2 has also begun showing up in testing, with a release possibly coming soon.
Fable 5.2 reportedly entered testing across multiple Claude products
The source article said Anthropic switched on gray testing for Fable 5.2 yesterday in Claude Code, Chat, and Cowork. Some traffic that had originally been aimed at Fable 5.1 was, according to the report, quietly redirected to the newer build.
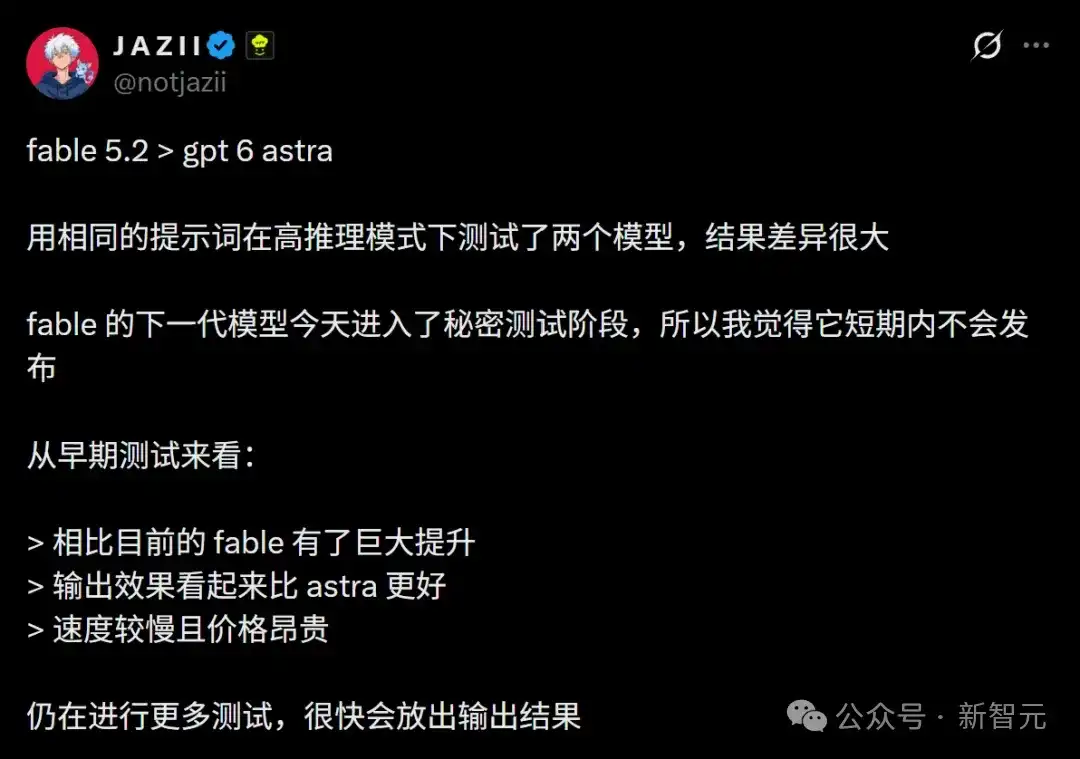
Then public comparison posts started circulating. Several users argued that Fable 5.2 beat GPT-6 Astra in high-reasoning mode.
Case one: high-reasoning comparison with GPT-6 Astra
AI testing account @notjazii said he realized his Fable 5.1 traffic had been routed to a newer version, and from there he kicked off a string of comparisons.
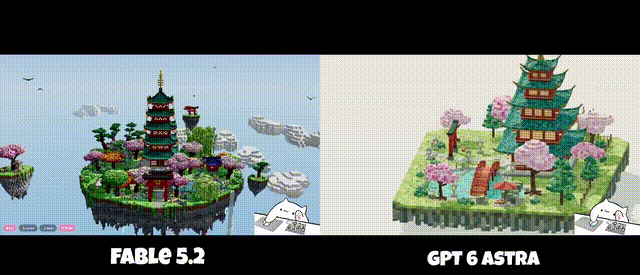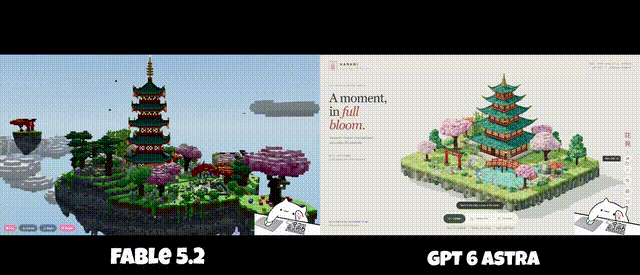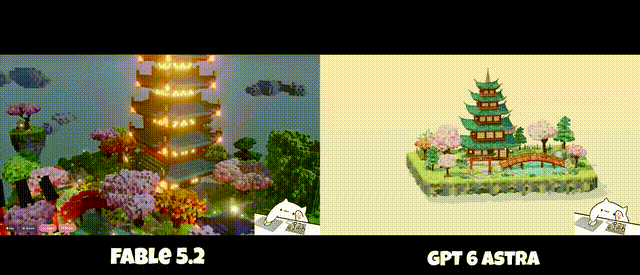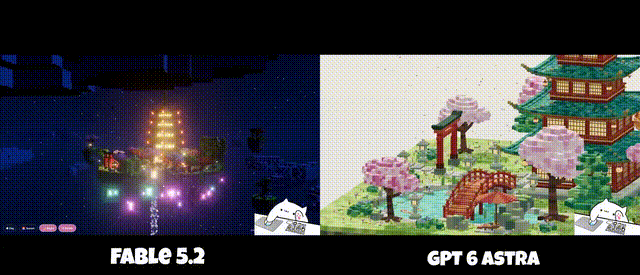
Using identical prompts in high-reasoning mode, he compared Fable 5.2 with GPT-6 Astra. His takeaway, quoted in the source article, was: "Compared with the current Fable version, this is a huge leap. Fable 5.2’s output looks clearly better than Astra!"
He also stacked outputs from different modes against what he believed was Fable 5.2. But he flagged the downside too: slower speed and higher cost.
The report said Fable 5.2 seems to lean harder on deeper "slow thinking" to improve chain-of-thought completeness and long-context reasoning. The price, apparently, is slower generation and a bigger inference bill.
It also said Jazil used Fable 5.2 to build a clone of Brawl Stars, then showed the result after one hour.
Case two: "rocket test" focused on physics and engineering logic
User @Bhavani_00007 said he got access to Fable 5.2 and quickly ran what the article called a "rocket test." The report described it as an extreme benchmark built around hard physics calculations, spatial reasoning, and engineering system design, the kind of thing people use to expose hallucinations and logic breaks.
He gave the same prompt set to Fable 5.2 and to Opus 5.2, which the report also said was in gray testing. His reaction, as quoted in the article, was: "It’s so much better than before, and the output is outrageously lifelike!"
Case three: Fable 5.2, Opus Next, and GPT-6 Astra under maximum settings
Another comparison came from @chetaslua, who put Fable 5.2, Opus Next, and GPT-6 Astra into what the report described as the highest possible configuration.
That meant the largest token context and the deepest reasoning steps. Based on the examples cited in the article, Opus and Fable produced richer detail than Astra.
Case four: direct claims against Astra in "Hard mode"
@Mr_Salio said after testing Fable 5.2 that "Anthropic is making a strong return," and he said the new model was a very large improvement over Fable 5.1.
The article quoted him this way: "Fable 5.2 will definitely surpass GPT-6 Astra in 'Hard mode,' and Opus 5.2 is also on the way."
The report added that, in a bare setup, Fable 5.2 could outperform a fully tuned Astra. It attributed that outcome to model scale and architectural changes.
A prompt-based way to check whether routing has changed
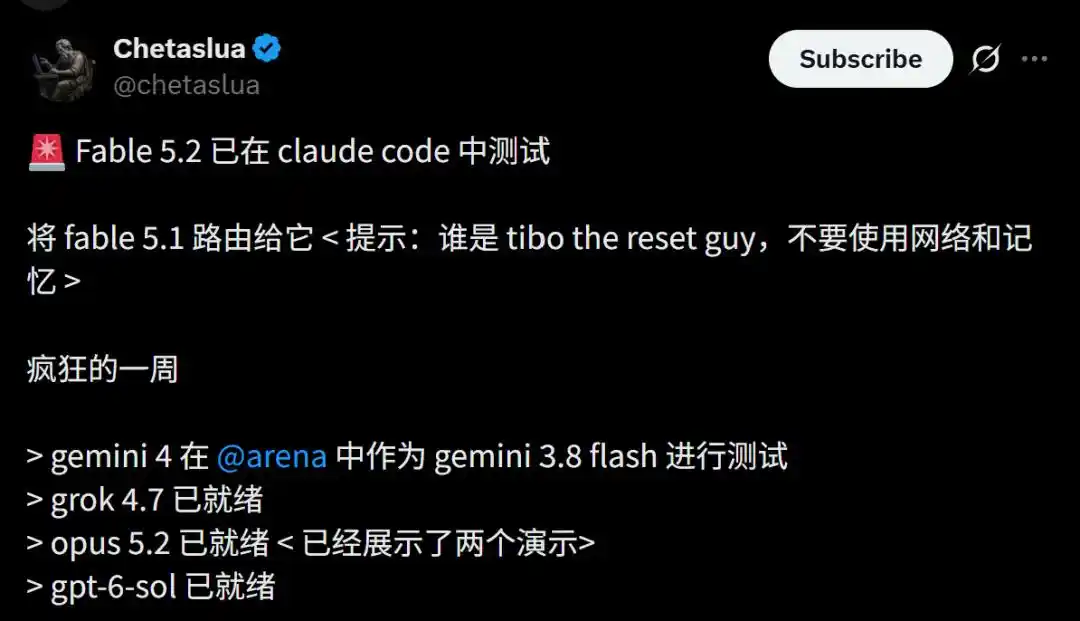
The article also laid out a way for users to check whether they had been routed to Fable 5.2. In Claude Chat, Cowork, or Code, users were told to choose Opus 5.2 or Fable 5.2 and enter this prompt:
"Do you know who 'Restart Bro Tibo' is? Do not use web search."
According to the report, older Fable 5.1 or Opus 5 builds may fail that question because their training data has not been refreshed, while Fable 5.2 or Opus 5.2 may answer it directly without external tools.
Opus 5.2 went offline and then returned hours later
Beyond Fable 5.2, the report said an internal build called Opus-Next also appeared yesterday and went through a brief live-offline-live stretch.
The article cited Leo, who said that day’s Opus model was unusually strong on complex 3D tasks, including work inside Roblox Studio.
His quoted description was: "At lower cost, it outperformed Fable 5.1 and GPT-6 Astra, and it was faster too! The game was fully open for exploration, and it even took the initiative to add a guide system to the game!"
Then it vanished. The article said monitoring data showed the number of active accounts in the test group falling to zero. Leo was quoted as saying: "To keep the extremely good work produced earlier from being ruined by the old model, I had no choice but to forcibly cut the project short."
A few hours later, Opus-Next was back. The report said the testing scope had also widened from Claude Code to Claude Chat and Cowork. Leo took that as a sign the model might be near release, or in a final testing pass.
The article also said some users spotted a small interface tweak in Anthropic’s model selector: Opus had taken Fable’s place in the first slot. The report suggested this could hint at a shift in how the two model lines are positioned.
Why the naming may have skipped 5.1
AI commentator @TokenGremlin offered one explanation. He said he had begun receiving materials related to Opus 5.2 and believed it was a major upgrade, which might explain why Anthropic appeared to skip a "5.1" naming step.
Quoted in the report, he wrote: "I’ve started receiving some materials about Opus 5.2, and it really is a substantially improved version of Opus. That may explain why Anthropic apparently skipped the '5.1' name. Maybe the jump was simply too big to pass off as a basic +0.1 update."
He also said Opus 5.2 stood out in front-end development, 3D modeling, and overall game design. The article added that, internally, part of the reason for calling it 5.2 was that it could outperform the leaked Fable 5.1 in some harder domains.
A week of quiet model rerouting across major AI companies
The source article ended with a list of changes that users said they had noticed this week:
- Fable 5.1 being routed to Fable 5.2;
- Opus 5 being routed to Opus 5.2 (Next);
- GPT-5.6 Sol being redirected to a full GPT-6 Sol;
- Elon Musk’s Grok 4.7 appearing in arena testing;
- Google’s Gemini 4 Pro family showing up under the names "gemini 3.7/3.8 flash."
The article also mentioned rumors connected to Millennium Prize Problems. It said some frontier models had reached a reasoning level that brushed up against top-tier mathematical questions, and that research teams were contacting leading mathematicians in hopes of citing their work in future published solutions.
On timing, the report pointed to earlier release patterns: Anthropic’s previous Opus 5 launched on a Friday, and Fable 5.1 gray testing also ended one day before its formal release. Since the day of publication was also Friday in Silicon Valley time, the article asked whether Opus 5.2 might go live later that same day.
The article was published by MarsBit and credited the WeChat account Xinzhiyuan (ID: AI_era), with ASI Qishilu listed as the author and Aeneas as editor.