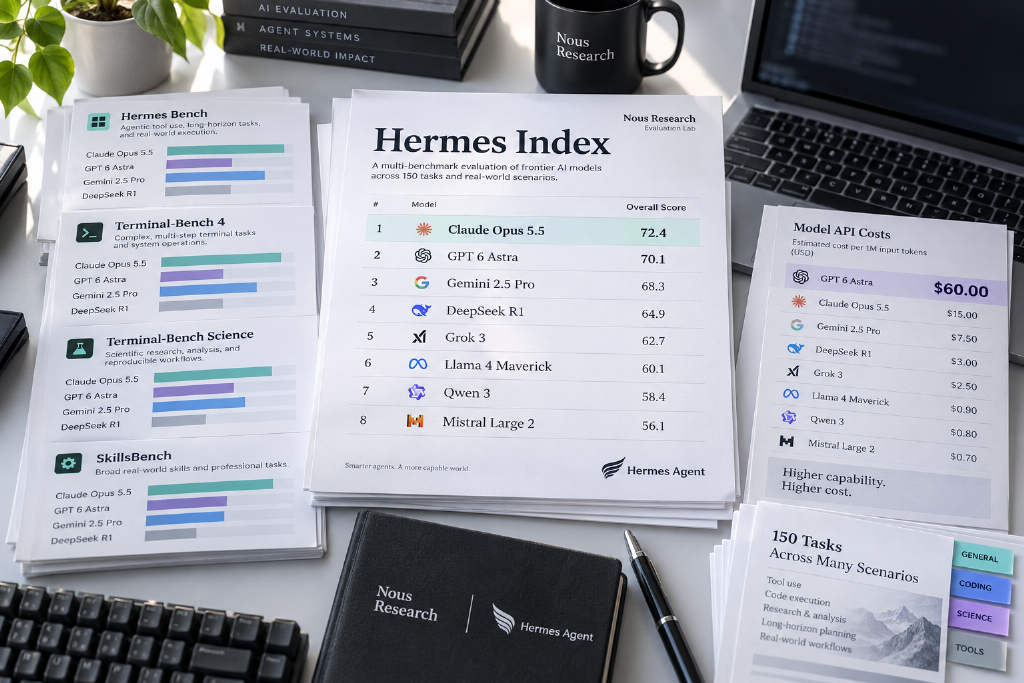
Nous Research has launched Hermes Index, a new leaderboard for Hermes Agent that compares how different models perform under the same operating framework. In the first release, all models were tested with a unified Hermes Agent setup, and any model that supports adjustable reasoning intensity was set to high. Rankings are based on the average score across four benchmarks: Hermes Bench, Terminal-Bench 4, Terminal-Bench Science, and SkillsBench, with average cost per task tracked alongside performance.
Hermes Bench is a new in-house evaluation from Nous Research covering 150 tasks across 25 scenario categories, including skills, research, charts and creative work, memory, tool use, and safety. The agent interacts directly with workspaces and real files, and scoring is based on generated files, task status, and tool-use logs. The first edition tested 14 models. Claude Opus 5.5 placed first with 63.31 points, GPT 6 Astra came second with 56.25, and Claude Sonnet 5.5 ranked third with 53.14.
On cost, GPT 6 Astra was the most expensive model on the board at $11.61 per task. Claude Opus 5.5 averaged $4.99 per task, while Claude Sonnet 5.5 came in at $2.82, though some of those figures were marked provisional by the official source. Among lower-cost models, DeepSeek V4.1 Flash scored 36.91 at $0.259 per task, and GPT 6 Luna scored 33.89 at $0.141. Both landed on the cost-performance Pareto frontier.
Nous Research has launched Hermes Index, a model leaderboard for Hermes Agent, to compare how different models perform inside Hermes.
All models were tested under the same Hermes Agent runtime framework. For models that support adjustable reasoning intensity, the setting was standardized at high. The ranking uses the average score across Hermes Bench, Terminal-Bench 4, Terminal-Bench Science, and SkillsBench, while also tracking average cost per task.
Hermes Bench covers 150 tasks
Hermes Bench is a new evaluation created by Nous Research. It includes 150 tasks across 25 scenario categories, covering skills, research, charts and creative work, memory, tool use, and safety. The agent works directly with the workspace and real files, and scoring is based on the files it generates, task status, and tool-use records.
The first version of the leaderboard tested 14 models. Claude Opus 5.5 ranked first with 63.31 points. GPT 6 Astra placed second with 56.25 points, and Claude Sonnet 5.5 came third with 53.14 points.
Astra posts the highest per-task cost
On pricing, GPT 6 Astra averaged $11.61 per task, the highest on the entire board. Claude Opus 5.5 averaged $4.99 per task, while Claude Sonnet 5.5 averaged $2.82. Some of the data for those two models was still marked as provisional by the official source.
Among lower-cost models, DeepSeek V4.1 Flash scored 36.91 with an average cost of $0.259 per task. GPT 6 Luna scored 33.89 at $0.141 per task. Both models made the cost-performance Pareto frontier, meaning there is no model with both a lower price and a higher score.
This article was originally published by Bit.Fan. For more cryptocurrency news and market insights, visit www.bit.fan. Disclaimer:
The market information, project data, and third-party content displayed on this platform are for industry information sharing only and do not constitute any form of investment advice or return commitment.
Cryptocurrency trading carries high risks. Users should fully assess their risk tolerance and make independent decisions. All profits, losses, and legal responsibilities are borne by the users themselves.