
A developer using the name hashfunction has published metadata for about 5.6 billion public TikTok videos on Hugging Face under the datasocial account, with the files available for anyone to download. The dataset covers a period from July 2014 through October 2026.
Metadata only, not the videos themselves
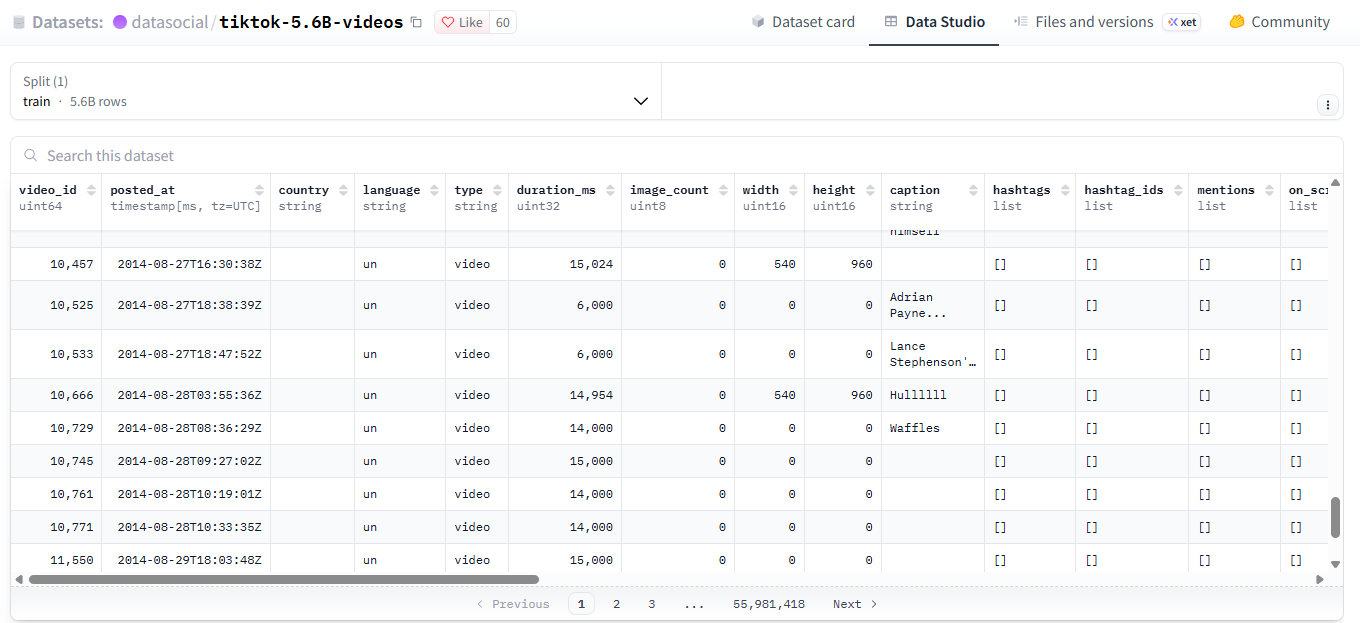
The release does not include footage. Each row contains a caption, hashtags, a sound ID, on-screen text, TikTok Shop product and seller IDs, and counts for views, likes, comments, shares, saves, and downloads. The full set comes as 460 GB of Parquet files, split into one file per month.
Some fields reflect TikTok’s own internal labels, including whether a video was flagged as AI-generated and whether TikTok kept it off the For You page. The report says the AI-generated field is often blank for older posts because those records come from an archive.
Open access on Hugging Face and datasocial.ai
The dataset is not gated. Anyone can pull it, and Hugging Face shows 1,181 downloads so far. It is also available online at https://datasocial.ai/.
Why does this matter? The report points to demand from AI developers. Captions, hashtags, sound IDs, and engagement counts across billions of posts can be used as training material for models that try to predict what goes viral on TikTok, what sells through TikTok Shop, which words and phrases perform well, and how people write in short-form video environments.
TikTok’s official access path is much narrower
TikTok’s Research Tools are available only to qualifying researchers at academic institutions in regions that include the United States, the European Economic Area, the UK, Canada, and Switzerland, along with some not-for-profit bodies in the EU. Access requires an application and approval.
Broader scraping is not allowed under the platform’s rules. Section 3.4 of TikTok’s U.S. terms of service bars the extraction of data from the platform with automated software unless TikTok gives written approval.
DataSocial describes how the collection worked
In its write-up, DataSocial says it reached TikTok’s private mobile API by generating device identities that passed as Android phones, reverse-engineering request signatures, and spoofing the TLS handshake. It says the system collected 3.23 billion creator profiles, 5.94 billion videos, and 2.8 billion comments in three weeks. According to that write-up, no login or account was used.
The free release also functions as a storefront. The dataset is licensed under CC BY-NC 4.0, and the card says it is free for research and personal use. Commercial use, creator profiles, and daily updates are directed to datasocial.ai, while the scraper’s source code is sold separately.
Scraping disputes are already being tested in court
The report notes that scraping battles are already in litigation. Reddit sued Perplexity and three data-scraping firms in October 2025, alleging an 「industrial-scale」 effort to harvest Reddit content for AI training. According to Law360, a federal judge in July largely declined to dismiss the case.
The claims that remain include DMCA allegations that SerpApi bypassed Google’s anti-bot protections. TikTok is not a party to that case, and the dispute concerns scraping through Google search results rather than a private mobile API.
What the dataset includes, and what similar sets already exist
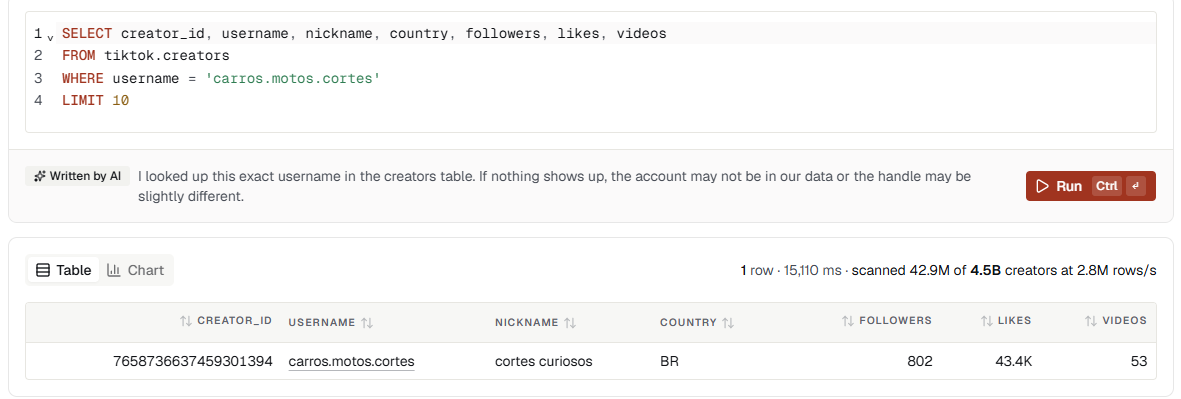
As described in the report, the rows include captions, music used, and several checkbox-style fields. There is no creator handle column, but the dataset still exposes a large amount of information, including captions, hashtags, and people mentioned in a video. The report also says the user ID is in fact available in Datasocial.
This is not the only large TikTok dataset on Hugging Face. Copies of a 4.5-billion-video set, also described as collected from TikTok’s mobile API, are already hosted there.
The data is free for non-commercial use. The code used to collect it is priced at $1,699.