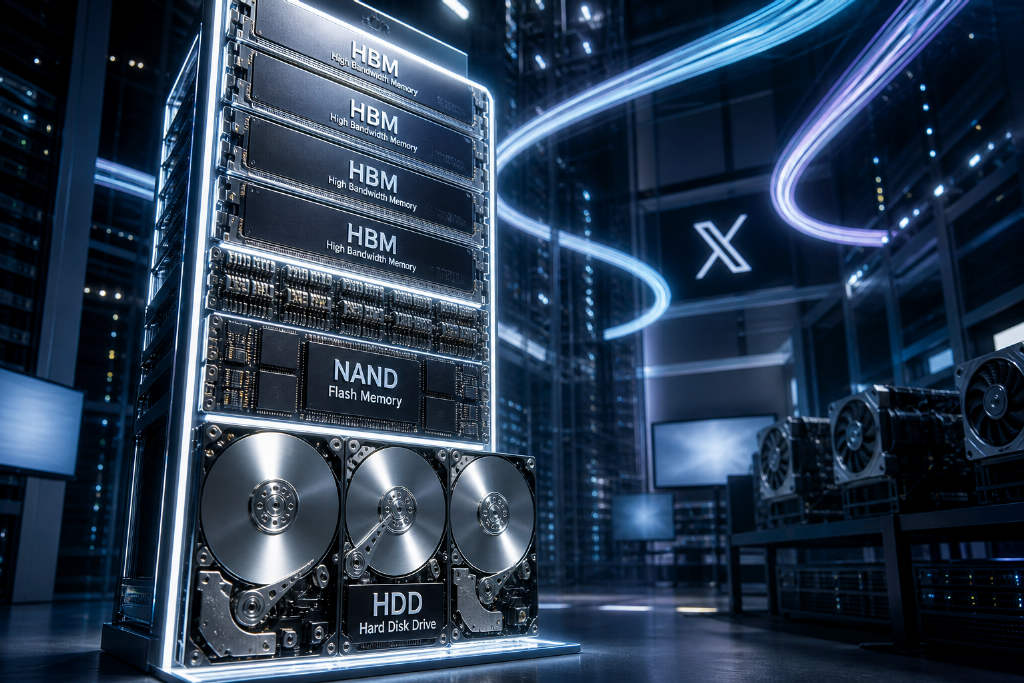
AI infrastruc2026-09-29 06:19:19AI Infrastructure Spending Shifts Toward Optical Interconnects as GPU Share FallsTwo research reports from Jefferies and Bank of America argue that the cost structure of AI infrastructure is changing as rack-scale systems grow larger. Jefferies’ bill-of-materials analysis of NVIDIA AI rack platforms shows GPU costs taking a smaller share of total rack spending, falling from 62.5% in the early GB300 NVL72 generation to 46% in the Rubin-era NVL576 Pod. Over the same period, total procurement cost for a single rack jumped from $4.16 million to $55.25 million, while networking and fiber interconnect rose from 8.6% to 22.4%, or more than $12 million in absolute terms. Bank of America, citing an interview with former Microsoft engineering vice president Fran Cardells, said the shift is tied to inference workloads rather than training. In agentic AI systems, KV cache must hold prior token sequences, enterprise context, guardrail rules, and agent decision logs, and in some cases can reach 10 times the size of model weights. As context windows expand from about 128K tokens toward 1 million tokens and multiple agents run at once, memory demand keeps rising. Cardells said the bottleneck is no longer simply how many GPUs a system has, but how quickly data can move across GPUs, memory, and storage. Both reports point to optical networking, photonics, memory pooling, and related infrastructure as areas the market may still be underestimating.370
SemiAnalysis2026-09-22 04:50:22SemiAnalysis says memory bandwidth matters more than capacity in AI inference, with scheduling emerging as a core layerSemiAnalysis has published a report breaking down the underlying architecture of large-model inference services, arguing that the rise of mixture-of-experts, or MoE, models has turned inference into a multi-stage pipeline rather than a single compute task. The report describes that pipeline as consisting of Prefill, Midfill, Decode Attention, and Decode Experts, with each stage placing different demands on compute, memory bandwidth, and networking. Its central conclusion is that, in most inference scenarios, memory bandwidth carries more economic value than raw capacity. According to the report, high-bandwidth memory can improve token generation efficiency, while idle HBM mainly adds cost. SemiAnalysis also projects that by 2027, a single pipeline stage may require roughly 400 GB to 500 GB of local fast memory, though processed KV cache should be moved to CPU DRAM and lower-cost network storage to avoid tying up scarce HBM resources. The report also identifies the scheduling layer as a critical part of inference infrastructure. It says Prefill and Midfill are relatively predictable in runtime, while decode latency is more variable and can create backlog and delay-feedback oscillation. SemiAnalysis further compares integrated and disaggregated architectures, and includes simulator-based projections for Kimi K3 on Nvidia B200, B300, and GB200 systems.400
TypeSafe2026-09-21 08:43:37Jev team shares Coding Agent draft centered on per-turn context selectionTypeSafe founder Diogo Almeida has published a design draft for a Coding Agent and said the community is free to experiment with it directly. He also said the team likely will not have enough time to build every idea in the proposal themselves. The main change in the draft is how context is handled. Instead of keeping prior chat history, tool outputs, and code state attached until the context becomes too long and must be compressed or reset, the proposal suggests that the agent should decide again on every turn what it actually needs to keep. That includes whether to reuse the current cache or assemble a better context set, which items should remain in full, which should be reduced to summaries, and which should be dropped entirely. Almeida argued that many current agent designs are being constrained by KV Cache in reverse. He gave examples such as routing a task to a cheaper model first and then back to a stronger model, only for the stronger model to reread a long context and erase the expected cost savings. He said the same issue applies when tool definitions stay in the system prompt for long periods and keep consuming space. Almeida is currently calling the approach "Meta-attention."500
SanDisk2026-08-15 03:40:06Wall Street Reprices SanDisk as AI Inference Lifts NAND Into the Infrastructure TradeAfter SanDisk’s investor day on Aug. 15, several Wall Street firms recast the company as part of the AI infrastructure build-out rather than a name tied mainly to consumer-electronics memory cycles. JPMorgan resumed coverage with an Overweight rating and a $2,250 price target, arguing that inference demand for KV Cache, enterprise SSDs and high-bandwidth flash is changing the demand profile for NAND. The bank also said SanDisk’s new multi-year commercial model agreements with large customers should improve demand visibility and help support margins while NAND supply remains tight. Citi kept its Buy rating and $2,100 target, pointing to the same themes: steadier revenue from long-term contracts and structural demand from AI data centers. Morgan Stanley took a more cautious line, saying the company’s high-margin targets may be difficult to execute, though it also acknowledged that a combination of supply shortages and AI demand could keep SanDisk’s profitability above historical cycle levels for years. The reassessment showed up quickly in trading, with SanDisk up about 6.5% on Friday, nearly 35% for the week and more than 60% over the past two-plus weeks. Micron, Western Digital and Seagate also moved with the broader storage chain.1620
Elon Musk2026-08-14 07:23:01Musk Agrees AI Agent Era's Real Bottleneck Is Memory, Not ComputeElon Musk has publicly endorsed a statement by Peter H. Diamandis, the futurist and XPRIZE founder, that memory rather than compute is the rate-limiting factor of the agent era. Musk replied that few people realize this. Diamandis's view holds that after large-scale deployment of AI agents, long-term memory, context memory and persistent memory will replace compute as the true bottleneck. Even with sufficient computing power, an agent that cannot effectively remember and call up information will have limited utility. The interaction was tracked by 动察 Beating and shared through its 24/7 AI news channel. The thesis connects to current memory and storage conditions: HBM demand remains in short supply, while rapid growth in KV cache and context storage is driving structural increases in NAND and hard drive demand, and memory is listed among the most critical, tightest links in the AI supply chain.2890
Marvell Techn2026-08-04 13:21:00Marvell unveils AI memory lineup spanning CXL expansion and photonic shared memoryMarvell Technology has introduced a new portfolio of memory solutions for AI infrastructure, targeting bottlenecks in memory capacity and bandwidth during Agentic AI inference. According to the company, the lineup spans server-class AI storage, rack-scale CXL memory expansion and pooling, and multi-cabinet shared memory built on optical interconnects. Marvell said growing model sizes, longer context windows, and rising KV Cache demand are making traditional tightly coupled compute-memory architectures less efficient for inference workloads. The company argues that memory disaggregation allows memory resources to scale more independently from compute, which can improve GPU utilization and reduce data movement latency. The launch includes the Bravera SC6 PCIe 6.0 SSD controller for AI inference storage, the Structera X memory expansion platform based on CXL, and the Photonic Fabric optical memory solution. Marvell said the Bravera SC6 is designed to help cloud providers move more KV Cache to high-performance SSDs and is expected to begin sampling in the fourth quarter of 2026. The company also said Photonic Fabric can support up to 32TB of warm KV Cache offload and deliver as much as 2x to 3x higher token throughput within existing data center space and power limits.1860
Google2026-07-24 09:25:16Google Unveils TurboQuant as Claimed 6x AI Memory Cut Hits Storage StocksGoogle Research introduced TurboQuant, a training-free compression method that it says can shrink LLM KV cache memory use by at least sixfold. The announcement pressured memory and storage stocks in the U.S. and Asia.280
SemiAnalysis2026-07-19 02:20:13SemiAnalysis says Kimi K3 cuts KV bandwidth, but AI network demand may still riseSemiAnalysis said Kimi K3 can sharply reduce KV-cache transfer bandwidth through its KDA-based design, but argued that this does not point to a major contraction in the AI networking market. According to the research firm, roughly three-quarters of Kimi K3’s network layers use KDA, which can cut KV-cache transmission bandwidth by as much as 10x versus a full global-attention model. Even so, the model’s overall infrastructure demands remain large. SemiAnalysis said Kimi K3 has 2.8 trillion parameters and still requires about 1.5TB of HBM bandwidth per forward pass even with MXFP4. To deploy the model profitably while maintaining reasonable interaction speed, operators would still need to connect large numbers of chips through high-bandwidth networking systems such as GB300 NVL72 and rely on WideEP for scaling. The firm added that WideEP distributes 896 expert models across multiple GPUs and performs token dispatch and result merging twice per layer in each forward pass, exceeding 120 operations in a single pass. By comparison, KV-cache transfer between prefilling and decoding happens only once per dialogue round, suggesting the bandwidth saved by KDA may be smaller than the additional scaling demand created by large expert-model architectures.1550