


Google DeepMind says standard implementations of Softmax and cross-entropy in PyTorch, JAX and textbook treatments contain numerical flaws that can erase training signals. Jon Barron, a principal research scientist at Google DeepMind, said the issue causes a tiny value to be rounded away in floating-point arithmetic, which means the more confident a model becomes, the easier it is for the correct gradient to disappear.
The team described the problem in an arXiv paper titled How to Fix Softmax and Cross-Entropy. In the paper, one of the failure modes is labeled “Softmax Collapse.”
The flaw sits inside a standard numerical stabilization step
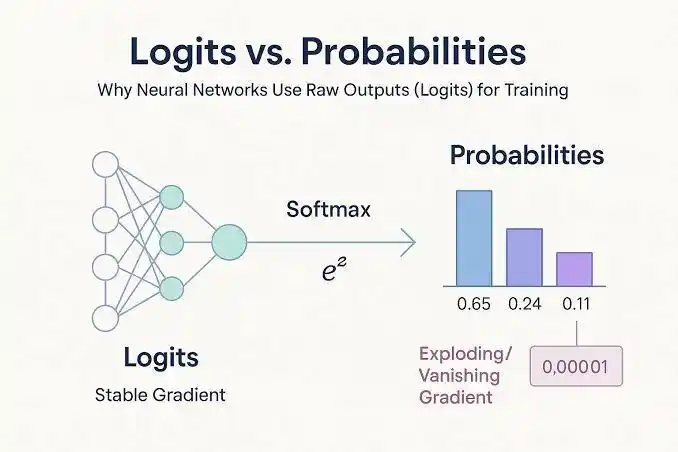
Softmax converts logits into probabilities, and cross-entropy measures the error used to train classifiers and large language models. DeepMind said the problem appears in the standard stabilization trick used to prevent overflow: subtracting the largest logit before computing the denominator.
That rewrite produces a denominator shaped like “1 + a very small number.” The more confident the model is, the smaller that number gets. In exact mathematics, the rewritten form is equivalent. In floating-point arithmetic, it is not always equivalent in practice.
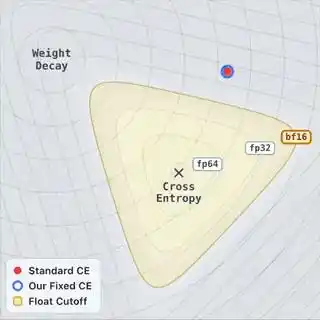
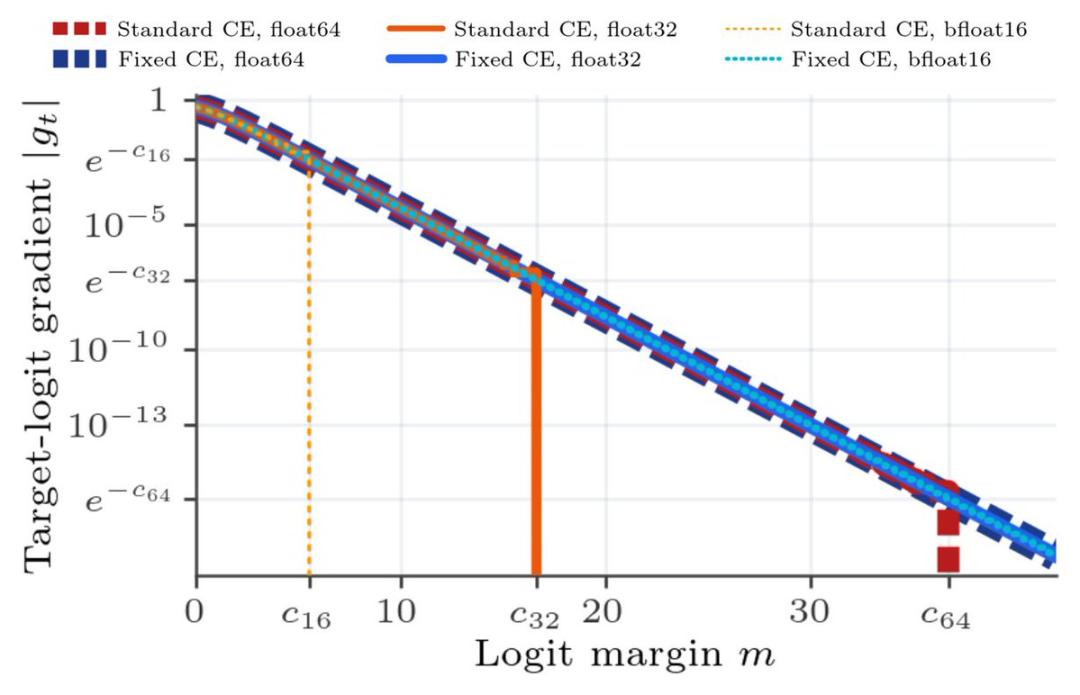
If a sufficiently small value is added to 1.0, the machine can round the result back to exactly 1.0. The paper says the cliff appears around 5.5 in bfloat16 and around 16.6 in fp32. Once that threshold is crossed, the gradient for the correct class can become exactly zero even though the model is still training.
Why the optimizer can make the instability worse
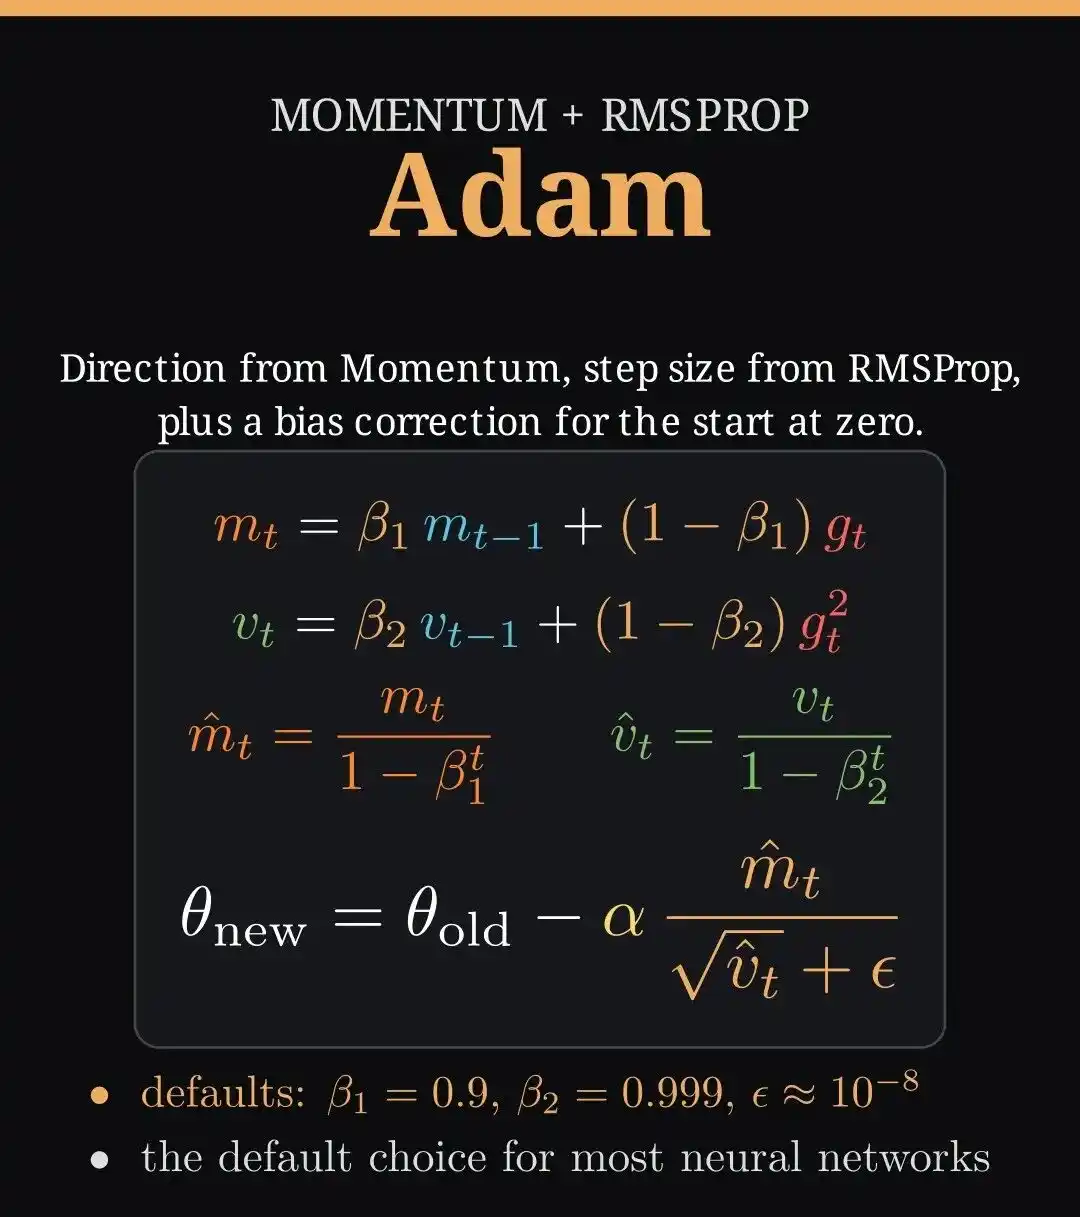
The paper says Adam can amplify the effect. Adam scales each update by a running average of recent gradients. If the gradient has been forced to zero for long enough, that average also shrinks toward zero.
When a real gradient finally reappears, the update is divided by a very small number. The result is a sudden jump in parameters and a spike in loss. Barron’s team links this behavior to the “slingshots” phenomenon that has been observed in grokking-style training runs and argues that at least part of that pattern comes from an implementation bug rather than a higher-level learning feature.
A second issue appears in distillation
The paper also describes “Softmax Cancellation,” a separate problem in knowledge distillation. In theory, if a student model exactly matches the teacher, the gradient should be zero.
DeepMind says standard code often computes the two probability distributions separately and then subtracts them. Rounding error can leave behind what the paper calls a ghost gradient, nudging the student away from the correct solution even when it should stay perfectly aligned with the teacher.
The proposed fix is to work in log space and use expm1 and log1p. Under that formulation, the gradient remains exactly zero when the student perfectly matches the teacher.
Barron outlined the rewrite in an X post
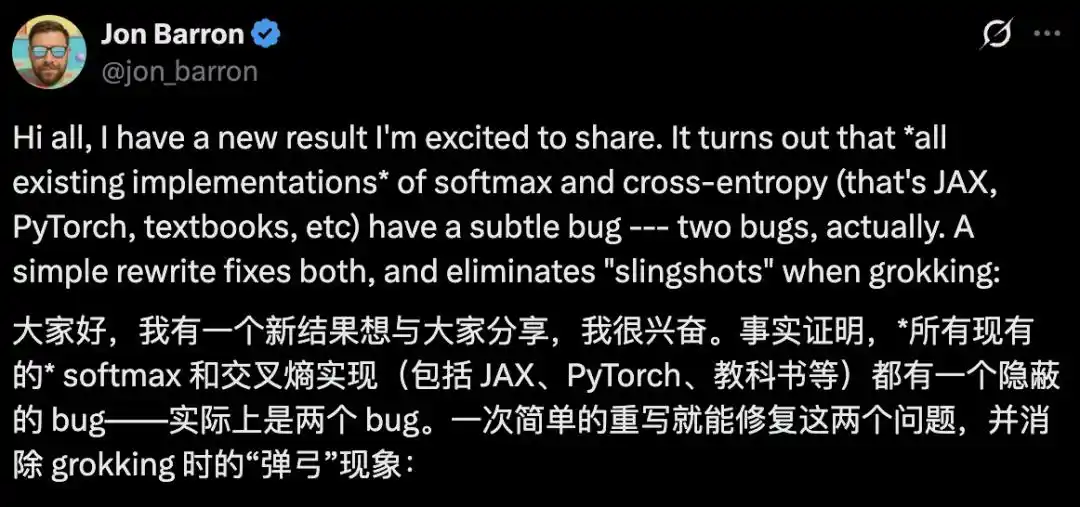
Barron wrote on X: “It turns out that all existing softmax and cross-entropy implementations (including JAX, PyTorch, textbooks, etc.) have a subtle bug — actually two.” He added that a simple rewrite fixes them and removes the “slingshot” effect seen during grokking.
- For cross-entropy, the fix for collapse is to pull the target term out of the sum, compute the margin with log-sum-exp, and return the softplus of the negative margin. The core rule is to avoid adding an extremely small number to 1.
- For distillation, the fix for cancellation is to compute in log space with expm1 and log1p.
Reported test results show a jump from 93.3% to 100.0%
The paper includes experiments on the task a + b mod 31. Using the standard implementation, test accuracy in bfloat16 was 93.3% and highly unstable, according to the report.
After switching to the revised implementation, test accuracy rose to 100.0%. In the distillation test, the divergence between student and teacher stayed at zero and accuracy remained at 100%.
Gemini was credited with finding the bug first
The claim that drew the most attention came in Barron’s follow-up comment. He said Gemini Flash 3.7 first discovered and fixed the bug, Gemini Flash 3.8 carried out most of the experiments, and Gemini 4 Argon drafted the paper and figures. Barron said his role was to review the work aggressively until the content was solid.
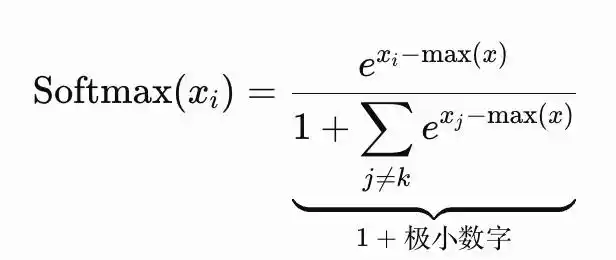
That account places Gemini at the center of the discovery, the fix, much of the experimentation, and the first draft of the write-up.
An independent engineer said he reproduced the mechanism in PyTorch
On Oct. 24, independent engineer Satyajit Ghana said he had fully reproduced the two bugs in PyTorch. He said he reproduced them on CPU by printing intermediate values, ported the fix, and confirmed the fp32 results reported in the paper.
His conclusion was direct: “Regardless of other details, the mechanism is unambiguously confirmed.”
The report ties the finding to earlier numerical failures
The article also points to earlier cases where lost precision had serious consequences.
In 1965, University of Toronto professor William Kahan warned in Communications of the ACM that repeated addition accumulates rounding error. He wrote that summing one million numbers could cost six significant digits. His solution was to keep an extra variable that stores the lost error and adds it back later, now known as Kahan summation.
He left a line that the article describes as prophetic: “Double precision will be widely accepted soon as a substitute for cleverness in the solution of numerical problems.”
In 1991, during the Gulf War, a U.S. Patriot missile battery failed to intercept an incoming Scud missile. The missile struck a barracks and killed 28 U.S. soldiers. A later U.S. General Accounting Office report said the system clock measured time in tenths of a second, but the register used to convert that time into a real number was only 24 bits long, allowing error to accumulate. The figures cited in the article say the error reached 0.02 seconds after 8 hours, corresponding to a 55-meter distance error, and 0.34 seconds after 100 hours, corresponding to 687 meters.
In October 1994, Lynchburg College mathematics professor Thomas Nicely found that a Pentium chip and an older 486 processor produced different results while computing the reciprocal sum of twin primes. He traced the problem to the Pentium floating-point division unit, where five entries were missing from a lookup table. Intel later agreed to replace chips for all users without conditions and took a $475 million charge in January 1995.
The article places DeepMind’s finding in that same line of numerical caution: the issue was clearly identified in 1965, it contributed to a deadly failure in 1991, it caused a major commercial loss in 1994, and in 2026 it has surfaced again inside some of AI’s most widely used functions.
References
The cited references include the arXiv paper and an X link shared by Brian Roemmele.